Posts
Making Agents Work For You : Getting Familiar
Introductory Series In Making Agentic Workflows
On This Page
This will be a series of posts because I want this to be as practical as possible, and beacuse of that an attempt to capture this all in a single post would be something that I’m only ever going to do when I’m not in my right mind.
Tentative split is like this :
- This post : Talk about how I started and my perception before and after the work. Also give some introductory ideas and jargons.
- Next post : Get things running. Write a very basic hello world style harness.
- Third post : Get some tools in. Introducing problems and a goal to the agent and watching it use the tools to achieve the goal
- Fourth post : Working with a remote inference (current plan)
Fourth post:Experimentations on tool usage and prompts. Understanding the world the agent experiences. (initial plan)
- Final post : Giving agent a full problem to solve
I will be writing this series of posts as if I’m talking to a newbie because I myself started as a newbie.
Contrasting Ideas
At the start of this year, I was very skeptical of the idea of an agent doing all job. I still am! I’m only skeptical though, I don’t have full proofs of either side of the answer. I only have arguments to make for the side of answer I want to believe in. Because of me being skeptical, I started exploring late than others.
Almost mid-year I was using agents to work because I used one time and I realized the potenial of speeding up my work. ASU (my college) gave students free access to OpenAI frontier models and we had a blast using frontier level intelligence. It was fun while it lasted, the access got stricter later on. Some people had already seen the potential and made the most of it while they could.
Past mid-year, after DEFCON, I realized I had my Mac Mini lying around and stays mostly off. I also knew that in today’s world, if you can put some compute power to good use, you can profit out off that. I’m also an avid homelabber and I host almost all of the services I nowadays use. I own the data, I own the infrastructure! What about LLMs though? I neither own the data and neither the infrastructure!
How can I put a good use to this Mac Mini? This wasn’t my first attempt. I had tried LM Studio and llama.cpp with a few models before, and it didn’t stick. I expected it to just work, and never looked at how it worked or what works best. That turned out to be the whole problem. I was already having debates with my fellow PhD students about using AI (or SI??) agents for bug hunting. My stance was that using AI agents for hunting bugs and writing exploits is not a good idea (FYI, I have 0 record of finding bugs in a widely used software, and 0 record of any 0-day or even n-day exploits, I want to make that non-zero though). I was talking with people who are really good at what they do (v/s me who is a noob in bug hunting and exploitation). My stance was that bug hunting is done for having fun, having that dopamine hit every time you find and exploit a bug and get a CVE assigned for it and using an AI agent to do that takes away that fun from you.
Inception
After DEFCON, it just hit me that I can have that fun that I want to have, by writing the bug hunting workflow myself. It’ll be like writing a program that finds bugs in other programs. What if I can do my research work and learn some agentic bug hunting at the same time? What if I can do more things? I host many servers, what if I just use the agent to monitor service health for me and give me notifications on something serious?
At this time, I also had recently skimmed over some interesting blog posts that talk about how local models can compete with frontier models for bug hunting. The claim they made was that system can help complement solving the challenges faced by model. To be specific, this was the post that inspired me a lot : System Over Model : Zero-Day Discovery at the Jagged Frontier. In other words, model size alone is not a good heuristic of whether or not the model will be able to achieve a given goal in given time. They claim that how the model is asked to achieve the goal, and the set of tools at the model’s disposal also impact how good the model will perform.
Info
Infrastructure
I own a Mac Mini M2 24G RAM shared between GPU and CPU. This is one thing that I own (other than my knowledge) that in the span of the time I own, only increased it’s value. A case of not diminishing return. This machine is more valuable than the price I got it for.
Another interesting thing about this machine is that I got this machine only to deliver software for a client I used to work with. They wanted it on all platforms and I only had Linux back then. Windows was just an emulation away but Mac? They’ve made it near impossible to emulate MacOS now, especially on Apple Silicon.
Introduction
LLM v/s Agent
A LLM, short for Large Language Model is a neural network, AI model, that is trained to write like us humans. As a result of the language we speak, these LLMs also gained reasonable reasoning properties which allows them to reason through a complex task.
Info
For the purposes of this series of posts, you dont really need to understand how LLMs work. All you need to know is how to interact with them. Think of an LLM as a black box. You can interact with this black box, but never open it and know what it is. The irony is that it’s actually true in terms of knowing how the LLMs think. Scientists do know how to train and how to make the LLM do what they want to do, but once the model is trained, it’s a black box! So do not put too much stress on it right now.
An LLM becomes an Agent when it’s put inside a loop to solve a problem, achieve a goal. The goal can be something like reading an image and describing it, reading your mail and filtering spam, do web search for you to find out answer to some of your questions. Agents are expected to work until they achieve their goal. An LLM is just there to generate the text.
| An LLM answers in one pass. An agent is the same LLM in a loop, calling tools until the goal is met. |
Interesting part is that the way we’ve engineered work in computer science is through natural language itself! In other words, think of what you do when you have to install a new package in your linux machine? Think of what you do when you want to write a program that can play chess in place of you (stockfish!). You write commands in form of natural language! So can these LLMs and given a goal, and a set of tools, they can call these tools in succession, while reasoning through each step to find a solution for you.
This solution can be a computer program code, or a paragraph of text, or an image, or a video, or whatever you want the final result to be.
From now on I’ll use the terms LLM and Agent interchangeably, until unless explicitly stated otherwise. I just gave you the distinction because I thought it’s better to have it clear. Agents are LLMs but sitting inside a loop with a goal and some ways to achieve the goal.
Weights/Parameters
LLM’s learn by learning weights. Weights is nothing but a fancy word for a number like -0.0014, 0.9948, etc… They are mostly small numbers between -1 and 1. Nobody knows what these numbers actually mean, they just make the model work. It’s called learning weights because they start very dumb. They absolutely generate gibberish. Much like a new born baby, who does not even know how to talk. So when they are given a token and asked to predict next, they will generate anything, absolutely anything from their vocabulary. They are then told what they should’ve predicted and told how much they were wrong, and from that the models get corrected.
I’m talking as if the models correct themselves, but there’s much more to it. There are learning algorithms that do the actual training. These algorithms compute how much the agent was wrong and then update it’s weights. This process of first getting a value that the model generates (observed value), then comparing it with the expected value and then getting how wrong it was (in form of a value, called error value), is then used to mathematically find out which weights caused this wrong value, and those weights get slightly nudged to be more biased towards generating the expected value next time.
The total number of weights a model is said to predict how much thinking capacity it can have. Think of it as size comparisions of brain between different animal species. Even in the same species and same model size, intelligence can be very different. Like intelligence of two humans can be different based on what the’ve learned and which parts of their brain are activated, they brain size (i think it’s measured by grey matter or something??).
So when I say a 26B model, it means it’s a 26B weight (or parameter, both are used interchangeably) model, it has roughly that many learned weights. More weights just mean more ways the LLM learns to differentiate between complex sentences.
Token
A token is a single entry in the model’s vocabulary, the smallest unit of text the model can comprehend. It’s not always a whole word. It can be a whole word, a piece of a word, a punctuation mark, or even a single byte. For example, “unbelievable” might get split into “un”, “believ” and “able”. The model only ever sees these tokens, each identified by a number (its position in the vocabulary). More bigger vocabulary means the model has more entries to pick from, and a bigger table of learned weights to describe each entry. A model consumes this token and gives you a list of tokens that should come next. This part of giving your model a token and getting tokens out of it is done by inference implementations like mlx (for Apple Silicon on MacOS).
This process of consuming a token and giving out a list of tokens, is what we refer to as the token generation process. Your list of tokens will have an associated probability of which token is most likely to be next. There are also some configurable parameters that can make the token generation process a bit non-deterministic. If you want to learn about this parameters, look it up, but we won’t be really using it, and it’s not a big deal. It’s something you can experiment with to get desired results, but you have to desire that first!
Info
Token Generation
These models work by consuming all the tokens generated and provided in sequence. That is essentially how they predict what token should come next. If you’ve ever had a chat with an AI like Claude or ChatGPT or any other model, you can see this. Whenever you’ll write something to the agent, it will start generating word for word. That is not for fancy. The tokens are getting streamed to you. Streamed in the sense that the tokens are copied out of the GPU memory, decoded, and then sent to your browser/terminal client over whatever internet protocol you’re connected with. The speed at which the model can generate not only depends on how fast your GPU is, but also on how fast the memory bandwith is. The weights live in GPU memory, but the GPU can only do math on the few MBs that fit on the chip itself. So for every single token, all the weights the model uses have to be read from memory into the GPU’s compute units all over again. Copying the generated token out is nothing, it’s just a number (a few bytes). Reading gigabytes of weights per token is what takes time, and this is the part that decides your tokens per second. I’ve been getting around 20 tokens per second on average on my Mac Mini M2 for Gemma4 26b A4b Mixture-of-Experts model.
Info
Newer generations of Mac have higher bandwith but not my a very hihg margin. I’d expect Somewhere around 30-60 tokens per second on latest Macs, the reason being that they have higher memory bandwith than an M2. On a dedicated graphics card with a good memory bandwith with your DRAM, you can get about 80-120 tokens per second for dense models!
Know that the tokens are consumed by these models, and then it goes through lots of multiplications and addition operations along all the the weights/parameters it learned and finally some predictions (token with their associated probability of being next in seqeuence) come out.
Think of it this way. Our world has some things always true, and somethings that are conditionally true based on what context you’re asking question. Loosely speaking, addition encodes the always true nature of the world and multiplication encodes conditional nature. When the token goes in, it goes through lots of multiplications and attitions at once, and it keeps happening at different steps (called layers) and at each layer the values generated changes until it reaches the final prediction layer, and by the time it has reached the final prediction layer, the agent has finished it’s thinking process, which was basically just mutliplying and adding it with the learned weights.
So, at the final layer there are many predicted token each with their associated probability of being next, and your token decoding process can either select the token with highest probably or you can do some other stuff as well. There are some values you can tweak to get different results most of the time, or same results most of the time.
| One token at a time. The whole sequence goes back in at every step. (probabilities are made up for illustration) |
Mixture-of-Experts vs Dense Models
Think of a dense model as using all its brain power at once. When it reads a token, it’s brain’s working mechanism will forward the information to all parts of it’s brain. It’s called dense for exactly this reason, it uses all the parameters it learned for mutliplication and addition operations (Floating Ops) to predict the next token.
In case of a mixture-of-experts, the model wont use all it’s brain power at once. Instead the model is built like a court of experts sitting at a round table. The router decides, for every token, which few experts (each a smaller set of parameters) should work on it. The chosen experts each give their answer, and the router mixes those answers together, giving more weight to the experts it trusts more for this token. This essentially ends up doing less computation and hence generating faster results with mabye slightly less thinking power.
The analogy breaks in a few places though. There’s not just one court, but one at every layer of the model, each with its own router and its own experts. And the routing happens again for every single token at every layer, so the experts used for one token can be completely different from the ones used for the next token. The experts also don’t specialize in topics like “math” or “biology” the way we would expect. What each expert is good at is learned during training, and mostly we can’t tell what that is. For example, Gemma4 26B A4B has 128 experts per layer, and for each token it picks 8 of them plus one shared expert that always runs. That’s how it only uses about 4B of its 26B parameters for each token.
| Dense uses every weight for every token. MoE routes each token to a few experts per layer. (10 experts drawn, Gemma4 26B A4B has 128 per layer) |
So imagine a dense model as being a single person doing all the thinking, and a mixture of expert model as being multiple persons available for thinking, but depending on what task currently they’re working on, only a few of them get a say. The catch here is that the single person thinking in this case will do slow thinking (by design, it’s got bigger brain, so it will think about more ifs and buts and thens), and the court of people is having slightly less intelligent people but they think very fast as compared to the single very smart person.
This eventually also brings up the fact that you cannot say how good a Mixture-of-Experts model is, as compared to a Dense model. It also depends on what they’ve learned, how they’ve been trained on what they’ve learned, etc… and not only just on the model size.
The good thing about MoE (mixture-of-expert) models is that they are fast, and given that they have reasonable thinking power, they can fail fast and correct themselves fast. It all becmes a tradeoff, in one way or another and your workflow or harness has to be engineered around these different behaviors.
Quantization & Optimizations On FLOPS
When the agents do their learning, they are usually taught in high resolution, meaning the learned weights usually consume high bits per weight. Like 16 bits per weight or 32 bits per weight. Higher bits means higher resolution of learning, means the agent will have more clarity in thinking.
Performing computation on higher number of bits takes more power and time, so that can impact how fast the model thinks. For this, people came up with the idea of compressing the weights to lower bits, but keeping most of the information in the weights. Think of it like image compression. There’s high res images and then there’s JPEG. A 10MB image can be converted to 10KB or 100KB, looking almost the same until you zoom in.
For models, we learned that 4 bits is a good compression level and at that quantization level, the agent thinks reasonably good enough to be usable and useful.
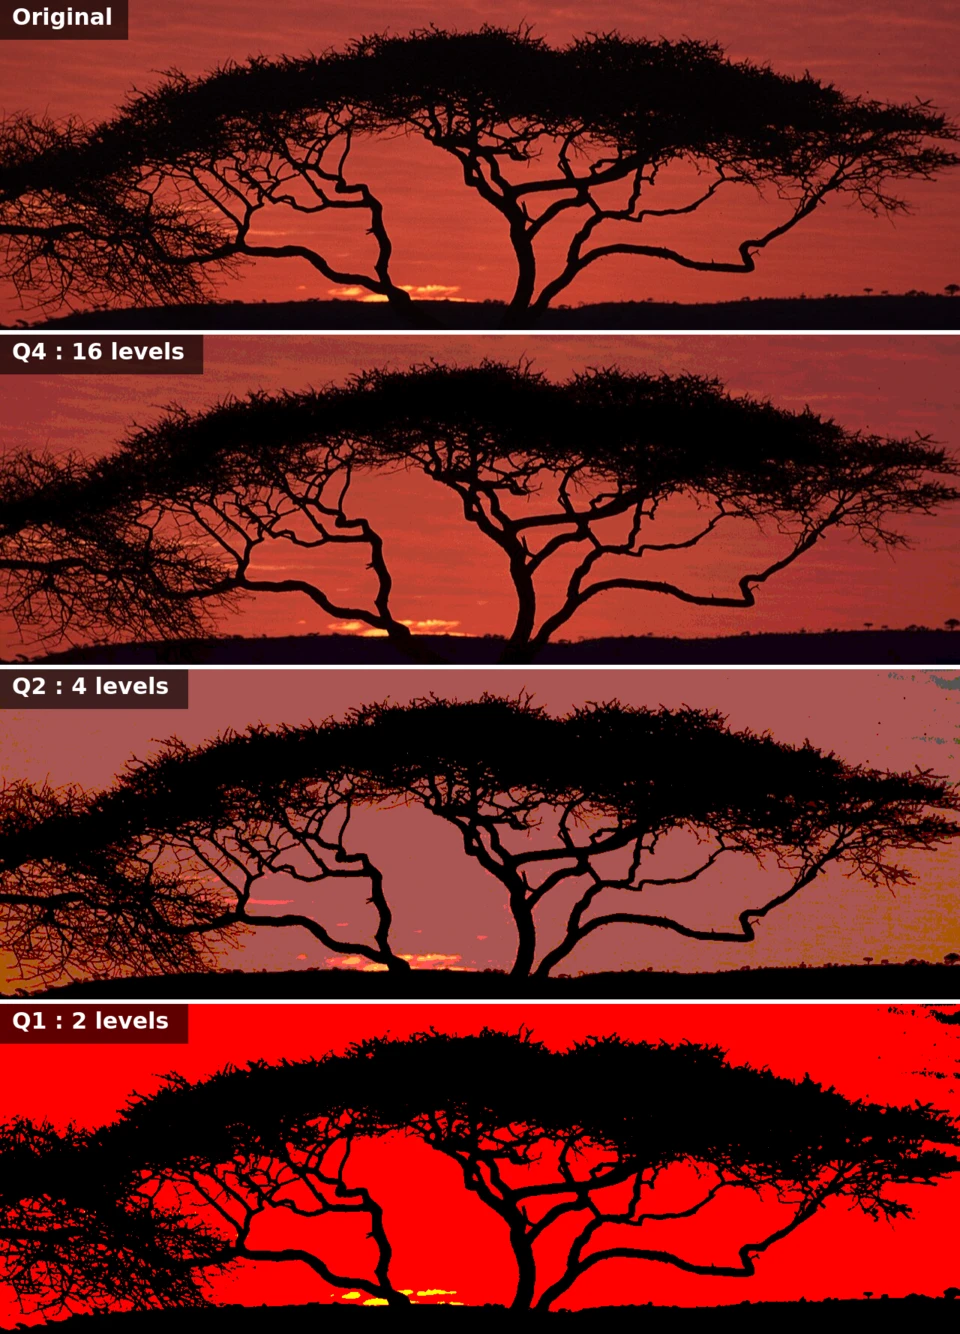 |
| Same image, each color rounded to fewer levels. Q4 still looks almost the same, Q2 and Q1 fall apart. (photo : Acacia At Dusk by John Storr, public domain) |

The good thing about quantization is that it reduces total VRAM space that the model will occupy while running. Quantizations can go from Q1, Q2, Q3, Q4, Q5, Q6, Q8, FP16, FP32. Not only that the model occupies less space, it also generates tokens faster, because there are fewer bytes of weights to read from memory for every token (remember the memory bandwidth part?). Given the shortage of RAM nowadays, and how limited sizes of RAM us normal people get (unlike billionare companies), we have to compromise on the model size and quantization levels.
We can not only quantize the model weights but also the KV cache (more on that next). Quantizing the KV cache lets you fit a longer context in the same amount of RAM.
Also, as for the compression parts, it’s only true if you are compressing the model weights after the training. There are also quantization aware training, and the model that I have been using is a QAT learned model. They sometimes are expected to work better than compressed models.
KV Cache
Remember that at every step, the whole sequence of tokens goes into the model to predict the next one. If the model redid all the math for every token at every step, generating the 1000th token would mean redoing the work for the 999 before it. That’s a lot of wasted work.
Turns out, a big part of that math never changes. At every layer, the model turns each token into two lists of numbers, a key and a value, which later tokens use to “look back” at it. A token can only look at tokens before it, so once a token is in the context, its keys and values never change. So we compute them once, store them, and reuse in every following step. That store is the KV cache. With it, each step only does the math for the one new token.
| Generating the token after “on”. Without a cache everything is computed again, with it only the newest token is. |
Think of reading a long book. Without a KV cache, every time you read a new sentence, you’d re-read the book from page 1. With it, you keep notes of what you’ve read so far and just read the next sentence.
The cache grows with every token in the context, and it lives in the same RAM as the model itself. For Gemma4 26B A4B that’s roughly 1-2GB of cache at 16 bits, on top of the model, on a machine with 24GB shared between everything. Quantizing the KV cache (mentioned above) can shrink this further.
Man did I not struggle with the harness speed until I came to know abut KV cache. I remember naiively writing
the harness and it was reading the whole context on each generate call. Soon after it I started vibe coding
because it was just taking too much time and I wanted to show something to my advisor soon so I can talk to him
about my progress. Anyways, I started vibe coding and I remember screaming out for the slow speed and exhausted
until AI caught me not using KV cache as optimization, and I know for sure that had I been watching myself
at that time I would’ve see a shine, a sparkle, a glitter in my eyes! I asked AI to add that in and it just sped
things up so fast! I was amazed! I will remember that always by the means of this post!
Context & Context Window
Think about what context means for us when we are normally conversing with other humans. It is essentially every set of related conversations and events that came before the current conversation. That decides what you’re gonna talk about next.
That is essentially what context means for agents as well, except that it’s very specific to what agents are working on right now, and there’s a limit to how much they can remember.
As I’ve been saying, the models generate token by token, but they dont just consume one token and generate the next, they consume a set of previously generated and consumed tokens, in sequence they appeared, to generate the next token. this seqeunce of previously generated and consumed tokens is what context for the model is.
A model usually starts with empty context, but you can start with a populated context as well.
Context window essentially decides the size of the tokens that live in the context. For frontier models at the time of this writing this, it is 1 million tokens. For the agent that i’ve been using locally, I usually cap it out at 100k tokens, beacuse of the VRAM limitation I got.
Think of context window as a short term memory the agent has. This memory lives in a very forgetful and volatile space in the sense that this can be changed or dropped anytime you want!
Context Compaction
So the context has a limit and agent has to keep going on. Obviously it will read and generate a lot and only so much can fit inside this limited space. How do we keep the agent keep going with knowledge of what it has been doing all this time?
I don’t exactly know how compaction works and I dont really wanna know at the time of writing this, I’m already quite exhausted and just wanna complete a first version of this series ASAP. I do have a general idea though, and this comes from my intuition that can be wrong.
The general idea is that once you hit your context limit cap, you ask an LLM to summarize parts of the context to keep the relevant information in the context. The quality of compaction will depend on how good the agent is instructed to do this. I myself tried doing this way but then later realized that for the intents and purposes of my use case I dont really need the agent to remember what it has been doing because it’s working in a loop, and every now and then the agent finishes it’s assigned work and gets new work, and the two works are not directly related.
The bad thing about making it work this way is that the summarizer agent can really mess things up sometimes. One challenge I faced was how the summarizer itself got stuck in the thought process. A low quality compacted context is bound to produce low quality thoughts in turns after compaction. This is the reason why even frontier model’s capability degrades after mutliple context compactions.
Keeping It Clean
So, I leanred the hard way that if two tasks are unrelated, just clear the context window, let the agent start fresh. People have been trying to solve this by storing some of the learned facts in files, because for example some things the agent learns along a task can be reused in some other task. If it has to spend time re-learning it again and again, it’s spending more time learning the same thing. This is also where skills and memory of agents come in, where claude code or codex will save memories that the agents themselves write, and boy do they shit in there!
I usually make very explicit rules about no comments in code, and no memories without my permission. The frontier models do respect it sometimes, but an extra git commit hook enforces this and make sure they doing shit around the codebase they’re working on, transferring false claims to the next session.
This is also where the idea of poisoning or degradation of contexts come in. Context management is a hard problem, and I think if this gets solved, how agents work will take another huge leap towards autonomous work. Right now the quality of work degrades with time (at least for me).
Prompt
A prompt is a message/content that you provide to the agent for reading. In case of visual models, this content can be an image, a sqeuence of images with timestamps (a video!). In case of textual models, this content is usually a message, but can be a binary file as well, converted to text first (like a hex dump or disassembly)! A binary is not exactly a natural language, but these LLMs are quite good at reasoning through these as well, finding patterns that are hard to catch human eye in limited time.
The quality of prompts decide a lot about how good the agent understands the final goal. Vague prompts can make the agent stuck in a loop or just give up. These are some very interesting behaviors that is visible in small models. I dont know whether these issues are present in frontier models or not, or if it’s present how they deal with it. What I do know is that some of these models come with a percentage chance of getting stuck in their thought loop during benchmarks.
Info
Prompts first get encoded into a sequence of tokens and then pasted into the context of the agent. The reading part of process also has to mark who each token is coming from. Was the token from system? from user? or was the token generated from model itself? These are called roles, and the model is trained to treat them differently.
Harness
Harness is the world where your agent will run inside. The general idea is that harness will contain tools and any other thing your agent might need to function well. Harness can have personalities of different agents. Like for example, when you are writing an agent for hunting bugs, you can have an agent personality more practical where it will prefer running code (because it’s instructed to), and one agent personality that will prefer reading code and finding bugs statically (again, because its instructed to act that way).
| The harness is the world around the LLM : instructions, tools, context and the loop. |
Imagine I ask an LLM to find me latest world population report per country. An LLM (no tools) will only be able to give you a correct and up-to-date answer if it got trained immediately before you asked this question to it. Usually the model will answer what it knows and sometimes even defend it when you say it’s incorrect! This happened because the LLM didn’t had any means to find up-to-date information.
Now, imagine using the same LLM but with tools (an Agent). Simple tools can be a tool to search and get relevant links, and another one to take a link and return only the page contents, and any other links the page mentions. Now, if you ask the LLM to give you “up-to-date” information, the harness will attach the list of tools to the message that you will send to the agent and it will then know about the presence of these means to fetch up-to-date information. Because of this change, the agent will now reason through your goal and decide when to use what tools and will have very high chances of getting you correct and up-to-date and complete answer.
Info
Inference
Inference is just the process of running an AI model on a machine. It’s the pipeline of going from input tokens to output tokens.
There are inference engines out there, like MLX, llama.cpp, that can run the models and handle the nitty-gritties of the token generation process for you. You just provide these engines the model weights and a config (a json file) that tells these engines about the architecture and default settings to use.
In my case I have an Apple Silicon M2, and I use MLX that is now considered quite mature on MacOS. When I started learning I used to read posts saying “now mlx is also quite good on Mac”. That gives me a hint about it not being quite good earlier and Apple did put some effort into their inference engine recently.
If I like one thing about Apple, its that their software engineering is appreciable! I’m happy that I got this machine back then and I’ll consider myself lucky that just by owning a machine that I got for a completely different purpose I get to learn low level stuff about a recent technology. I’ve always been interested in low level working of technologies and how to re-implement these things from scratch. It always helps me learn the issues that are faced by people and helps me reason better about the problems in the domain.
Selecting Good LLM Model
There are some properties I found in the models that I experimented with, that are desirable for it to function well given a task of average complexity.
- Ability to follow instructions. Sometimes agent will disregard the given instructions in order to achieve the goal. There’s inherently flaw in natural language that instructions dont capture the intent of the user. What we want the agent to do is understand both our intent and our instructions, but usually when writing instructiions, we do not capture the intent well and that leaves gaps where the agent can cheat through.
- Ability to reason logically for extended lengths
- Ability to call tools
- Low probability of getting exhausted (this is a topic that I will cover in the upcoming posts)
The Trend and The Engineering
For me this started with an experimentation, but turned out to be an engineering task for many reasons. One major reason is that models can behave very differently by a single rephrasing of the prompt and tool outputs it reads. A single tool failure can result in drifting away from goal in subsequent work. Given the ability, agent can drift towards finding out the cause of the tool failure rather than getting past it.
It’s engineering because you already have your methods, all you’re trying to do is to make it faster, stronger, reliable, robust. It’s also just wild to see the machine think like we do and follow your instructions, and with slight change of instruction it make fun of you, not by intent but by nature, by it’s design, and purely within the bounds of what the logic suggests. There’s different dimensions of engineering here : how you write your prompts, how you write your tools, how your agnet interacts with the tools, the personalities, the skills, the workflows and how they define the achievable goal (the loop).
I had a blast working on all this and learning all this. I didn’t know any of this when I started and I spent about two months stuck in a loop myself!
The Irony
Would you look at the irony now? I kept the agent in the loop and the agent kept me in the loop. We were both stuck in loops of my design. I was constantly making effort to slightly improve the harness so the agent wastes one less turn, and the agent was stuck in a loop because I wanted it to achieve the goal.
Now I’m probably gonna infect you with the virus that infected me for about the span of two months. So! I welcome you to the loop!
Resources
- System Over Model : Zero-Day Discovery at the Jagged Frontier - AISLE
- Gemma 4 Model Card - Google
- Neural Networks Series - 3Blue1Brown
- The Illustrated Transformer - Jay Alammar
- Attention Is All You Need - Vaswani et al., 2017
- Scaling Laws for Neural Language Models - Kaplan et al., 2020
- Training Compute-Optimal Large Language Models - Hoffmann et al., 2022
- The Super Weight in Large Language Models - Yu et al., 2024
- Scaling Monosemanticity - Anthropic, 2024
- Let’s Build the GPT Tokenizer - Andrej Karpathy
- Neural Machine Translation of Rare Words with Subword Units - Sennrich et al., 2016
- SentencePiece - Kudo & Richardson, 2018
- The Curious Case of Neural Text Degeneration - Holtzman et al., 2020
- Making Deep Learning Go Brrrr From First Principles - Horace He
- Efficiently Scaling Transformer Inference - Pope et al., 2022
- Apple M2 - Wikipedia
- Mixture of Experts Explained - Hugging Face
- Outrageously Large Neural Networks - Shazeer et al., 2017
- Switch Transformers - Fedus et al., 2021
- Mixtral of Experts - Mistral AI, 2024
- GLU Variants Improve Transformer - Shazeer, 2020
- A Visual Guide to Quantization - Maarten Grootendorst
- LLM.int8() - Dettmers et al., 2022
- GPTQ - Frantar et al., 2022
- Gemma 3 QAT Models - Google
- Gemma 4 QAT - Unsloth
- KV Cache from Scratch - Hugging Face
- Efficient Memory Management for LLM Serving with PagedAttention - Kwon et al., 2023
- KIVI : 2-bit KV Cache Quantization - Liu et al., 2024
- Lost in the Middle - Liu et al., 2023
- Context Rot - Chroma
- Effective Context Engineering for AI Agents - Anthropic
- Chat Templates - Hugging Face
- ReAct - Yao et al., 2022
- Toolformer - Schick et al., 2023
- Building Effective Agents - Anthropic
- OSX-KVM
AI Edit Disclosure
After making lots of edit myself and realizing I have knowledge gaps in certain places I asked an AI (or SI) to proofread the post and got a some good feedback and some false positives. I guarantee that I read all those suggestions and edits myself and carefully applied some edits over the AI edits myself.
What I got wrong :
- Tokens aren’t always whole words. They can be word pieces, punctuation or even bytes.
- Memory bandwidth matters because weights are re-read every token, not because tokens are copied out.
- MoE routers pick several experts per token, at every layer, and blend their answers.
- Weights are mostly, not always, between -1 and 1.
- Tokens can’t be quantized. The KV cache can.
- System, user and model are “roles”, not “modalities”.
- Quantization speeds things up mainly by reducing memory reads.
- Binary files must be converted to text (hex dump, disassembly) before a model reads them.
Small clarifications :
- Marked the addition/multiplication analogy as “loosely speaking”.
- Specified that emulating macOS is especially hard on Apple Silicon.
What the AI contributed :
- Made the quantization image from a public-domain photo (Acacia At Dusk by John Storr).
- Drew all five diagrams : LLM vs Agent, token generation, MoE vs Dense, KV cache and harness.
- Rewrote the KV Cache section, after I approved the draft.
- Found the resources and checked that each link loads and is free to read.
If you wanna talk about any of this! Write to me at hi@brightprogrammer.in, I’ll try my best to reach back.